Securing AI Models and Reviving Geothermal Energy
Securing AI Models and Reviving Geothermal Energy
A geothermal plant harnesses energy as the sun rises.
🇺🇸 A Vulnerability Exposed
So here's the deal. Large language models, like the ones you've been hearing about, they have a pretty big problem. They're vulnerable to attacks in a way that's kind of fundamental to how they're built. Researchers recently confirmed this flaw is not something we can just patch up with software updates or tweaks. It's baked right in. The models rely on vast amounts of data and complex algorithms, which makes them powerful but also exposes them to certain types of manipulation. Even small changes in inputs can lead to unexpected responses or even dangerous outcomes. This isn't just a hypothetical worry. It has practical implications for anything from automated customer service bots to more sensitive applications. This discovery tells us that securing these systems might be harder than we thought.
🇪🇸 Una vulnerabilidad al descubierto
La situación es la siguiente. Los modelos de lenguaje grande tienen un problema serio con su seguridad. Son vulnerables a ciertos ataques debido a una falla básica en su diseño que no se puede resolver fácilmente con actualizaciones de software. Esta vulnerabilidad está integrada en su estructura porque dependen de enormes cantidades de datos y algoritmos complejos. Eso los hace poderosos pero también susceptibles a manipulaciones sutiles que pueden causar respuestas inesperadas o peligrosas. Y esto no es solo una preocupación teórica; afecta aplicaciones reales como bots de servicio al cliente automatizado y aplicaciones más delicadas. Este descubrimiento nos dice que asegurar estos sistemas podría ser más complicado de lo que pensábamos.
Como Afiliado de Amazon, obtengo ingresos por las compras adscritas que cumplen los requisitos aplicables.

Complex circuits inside an AI model server.
🇺🇸 Context We Already Knew
Before this discovery, there was already buzz about the security of AI systems. People knew they were not impenetrable fortresses. Many in the tech world have been vocal about the risks and challenges of deploying AI broadly without foolproof safeguards. There were reports and papers warning us language models could be tricked or misled under certain conditions, but the full scope wasn't entirely clear until now. AI ethics discussions often touched on these vulnerabilities, too, focusing on issues like bias and security gaps long before any researcher pinpointed this exact flaw.
🇪🇸 El contexto que ya conocíamos
Antes de este descubrimiento, ya había preocupaciones acerca de la seguridad en sistemas de inteligencia artificial. Sabíamos que no eran fortalezas inexpugnables y que había riesgos al desplegarlos sin medidas seguras infalibles. En el mundo tecnológico, muchos alertaron sobre estos desafíos, mencionando casos en que los modelos de lenguaje podían ser engañados o desorientados bajo ciertas condiciones específicas. La ética en IA solía abordar estas vulnerabilidades, centrándose en problemas como prejuicios y brechas de seguridad mucho antes de que los investigadores identificaran esta falla precisa.

AI model vulnerabilities shown in a network map.
🇺🇸 The Mechanism Behind It
Okay, let's break it down mechanically—these large language models are built on neural networks that learn from gobs of text data. They basically predict what word comes next in a sentence by understanding patterns in language data they've processed before. But here's where it gets tricky: if you subtly manipulate inputs—maybe by introducing weirdly phrased sentences or altering context—you can push these models off track entirely because their predictions depend heavily on context already seen by them, which means they can be led astray quite easily if someone knows what they're doing.
🇪🇸 El mecanismo detrás del problema
Vamos a desglosarlo mecánicamente: los modelos grandes de lenguaje se construyen sobre redes neuronales que aprenden de grandes cantidades de texto. Predicen qué palabra sigue en una oración comprendiendo patrones en el lenguaje procesado anteriormente. Pero aquí está lo complicado: si manipulas sutilmente las entradas—quizás usando frases extrañas o alterando el contexto—puedes desviar completamente a estos modelos porque sus predicciones dependen mucho del contexto ya visto por ellos, lo cual significa que pueden ser llevados por mal camino fácilmente si alguien sabe cómo hacerlo.

Engineers optimize energy output at a geothermal site.
🇺🇸 Impact on Everyday Life
Now let's talk about real-world consequences for folks like you and me. If large language models can't be fully secured against these attacks, that spells trouble for industries relying on them for automation and decision-making processes—think customer service chatbots responding incorrectly or financial systems making erratic choices based on manipulated inputs. Imagine getting wrong advice from an AI-based medical app because someone figured out how to exploit this vulnerability; it's not far-fetched anymore with this flaw out in the open.
🇪🇸 Impacto en la vida cotidiana
Hablemos ahora de las consecuencias reales para personas como tú y yo. Si no se pueden asegurar completamente contra estos ataques los modelos grandes de lenguaje, se avecinan problemas para industrias que dependen de ellos para tareas automatizadas y procesos decisionales—piensa en chatbots dando respuestas incorrectas o sistemas financieros tomando decisiones erráticas basadas en entradas manipuladas. Imagina recibir un consejo médico equivocado desde una aplicación basada en IA porque alguien descubrió cómo explotar esta vulnerabilidad; ya no es algo tan improbable con este fallo expuesto públicamente.

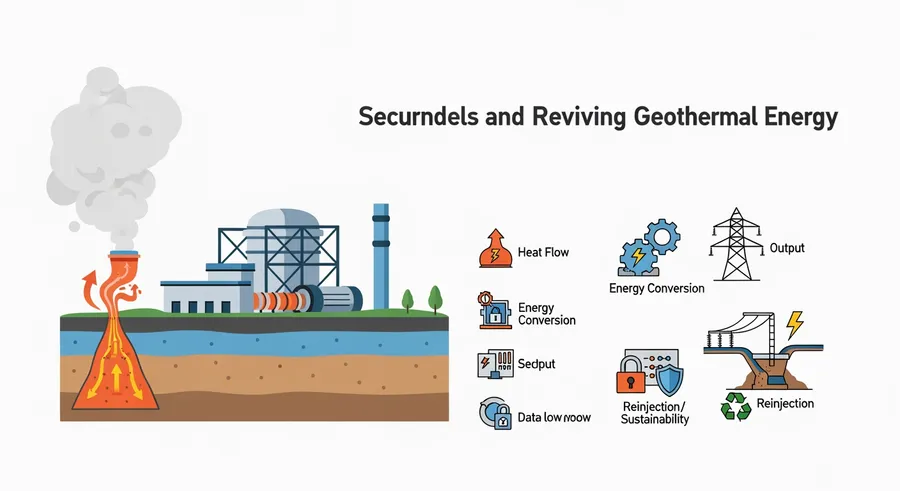
Geothermal plant structure revealed in cross-section.
🇺🇸 Lingering Questions
We still have so many questions here—big ones without easy answers yet—like how do we effectively secure these systems without fundamentally changing their architecture? Or can we find ways to detect manipulations early before any real damage is done? What about regulations—is there even a framework that can keep up with something evolving this fast? And then there's the matter of trust: how do we maintain confidence in AI when its foundational vulnerabilities are coming into clearer focus now?
🇺🇸 Preguntas pendientes
Todavía tenemos muchas preguntas sin respuesta clara aquí; grandes preguntas como cómo aseguramos efectivamente estos sistemas sin cambiar radicalmente su arquitectura o si podemos encontrar maneras para detectar manipulaciones temprano antes de provocar daños reales ¿Y qué pasa con las regulaciones? ¿Existe algún marco capaz mantenerse al día con algo que evoluciona tan rápido? Luego está el tema la confianza: ¿cómo mantenemos la fe en la IA cuando sus vulnerabilidades fundamentales están siendo más evidentes ahora?

Geothermal fields integrate with the environment.
🔗 Related Articles | Artículos Relacionados
Nuestro canal transmite datos curiosos de ciencia, IA, espacio y tecnología las 24 horas. | Our channel streams science facts, AI, space and technology around the clock.
▶ Ver transmisión | Watch liveOPEN YOUR MIND
Source: Source
Join the conversation